Why the ETL pipeline took ten versions
Hi, this is Vivek, building Contextflo. I share practical notes on getting answers from your data, a couple of times a month.
I asked for a simple ETL pipeline: pull a public dataset and its API into a warehouse so we could query it with SQL. The transform is about five hundred lines. It took ten versions to get right, and almost none of that was the code.
On paper the job is an afternoon. Read the API, page through the records, load them, put it on a schedule. Every one of those steps had a failure waiting inside it that no amount of design review would have caught, because the failure does not exist until you point real code at real data.
So I will put the lesson first: the hard parts of an integration are invisible until you run it. The ten versions were not a planning failure. They were the discovery.
The docs describe a different API than the one that answers
The first mistake was mine. The endpoint took a pagination parameter, I passed the obvious one, and it looked like it worked. It did not. The API silently ignored the parameter I sent and returned the first page every time. I read that as "this API only gives you a sample" and redesigned around a second source to get the full data.
The real parameter was in the spec the whole time. I had skimmed instead of read. That single wrong assumption cost hours of building the wrong thing.
The deeper point survives the embarrassment: even once I read the full spec, the spec was not the API. The document lists parameters. It does not tell you that one of them is ignored, that a large page size returns a gateway timeout, or that a filter you pass has no effect. You learn the real contract by calling the thing and checking what comes back against what it promised.
The data has edge cases you cannot enumerate
Then the loads started failing, each for a reason specific to one file or one record.
| What broke the load | The actual cause |
|---|---|
| One year rejected outright | It had 37 columns; the next year had 35 |
| Rows split in half | Free-text fields contained newlines the parser treated as row breaks |
| Parser gave up | Some values used backslash-escaped quotes the loader does not accept |
| A whole table refused to load | One record had "NaN" where every other row had an integer |
None of these are exotic. They are the normal texture of data entered by people over many years across many systems. The point is that you cannot list them in advance. You do not know a column will be "NaN" until the row with "NaN" in it fails the job. The defensive machinery you end up writing, tolerant parsing, explicit types instead of inference, a budget for genuinely broken rows, is a response to specifics you only saw at runtime.
The worst failures return success
This is the one that changes how you work. Several times a run finished, exited clean, and reported success while loading wrong data.
- The ignored pagination parameter meant one day loaded 45,000 rows that were 5,000 unique records repeated nine times.
- Under load the API returned short pages that were not the last page, so the loader stopped early and quietly dropped the rest of the day.
- For some dates the API returned nothing, so a day loaded zero rows and called it done.
A green checkmark told me nothing. The only way to know a load was correct was to check it against the source: row counts, distinct-id counts, whether every day in a range actually showed up. Verification stopped being a final step and became the work itself. If you are not comparing what landed against what the source claims to hold, you are trusting an exit code that has no idea whether the data is real.
The source punishes your assumptions
The obvious speedups made it worse.
Running the backfill in parallel to go faster overloaded the API, which returned timeouts, which is precisely what triggered the short-page truncation above. Asking for a big page or a wide date range to cut the number of requests returned a timeout instead of data, so everything had to be sliced into single-day requests. And a single day at the rate the API actually serves records adds up: a full year is millions of rows at a few hundred a second, which is hours, which does not fit inside a job timeout. That forced the whole shape of the pipeline to change from one big pull into a small daily window plus a slow, chunked, one-time backfill.
Every one of those constraints is a property of the live source under real load. You cannot feel any of them from the documentation.
You only learn this by running it
The tooling around the pipeline fought too. Build permissions were missing on the first attempt. Auth tokens expired every half hour and had to be replaced with a service account just to keep a long backfill alive. None of that is the data source, and all of it was part of the real cost.
Add it up and the pattern is clear. The transform is trivial. The ten versions came from a source that was inconsistent in ways no schema captured, that behaved differently than its own documentation, and that would hand back a 200 OK full of nonsense without complaint.
This is not a story about one bad dataset. It is what integrating a real, external, moving source looks like. You can design the clean version on a whiteboard in an hour. Getting it to actually hold takes days, because the source only tells you the truth when you run against it, and most of what it tells you is that your last assumption was wrong.
Here is a more in-depth look at Contextflo and how it works.
What is Contextflo?
Contextflo is a governed context layer between your data and the AI your team already uses. Connect your warehouse once, and your team asks questions in their own Claude or ChatGPT. The model writes and runs the SQL; Contextflo supplies the definitions, the per-user access control, and the audit that make the answers trustworthy. Your data never moves, and you do not need a data team.
How it works
Your team queries in their own Claude or ChatGPT over MCP, so you bring any agent rather than a locked-in bot, and every answer comes back with the SQL shown and access enforced per user.
See it on your own data.
Connect your warehouse and your team can ask Claude about it the same day, without waiting on a data team. Want a walkthrough first? Grab 20 minutes.
Book a 20-minute callSee how teams use Contextflo
Keep reading
Conversational analytics: 5 ways to set it up, compared
7 min read
How to connect Claude to BigQuery? What works and what doesn't in 2026
8 min read
How to connect Claude to Postgres without giving it write access
7 min read
How to build a BI dashboard with Claude that your team can actually trust
8 min read
How to give Claude read-only access to your database (it isn't always the default)
7 min read
You connected your warehouse to Claude, now what?
5 min read
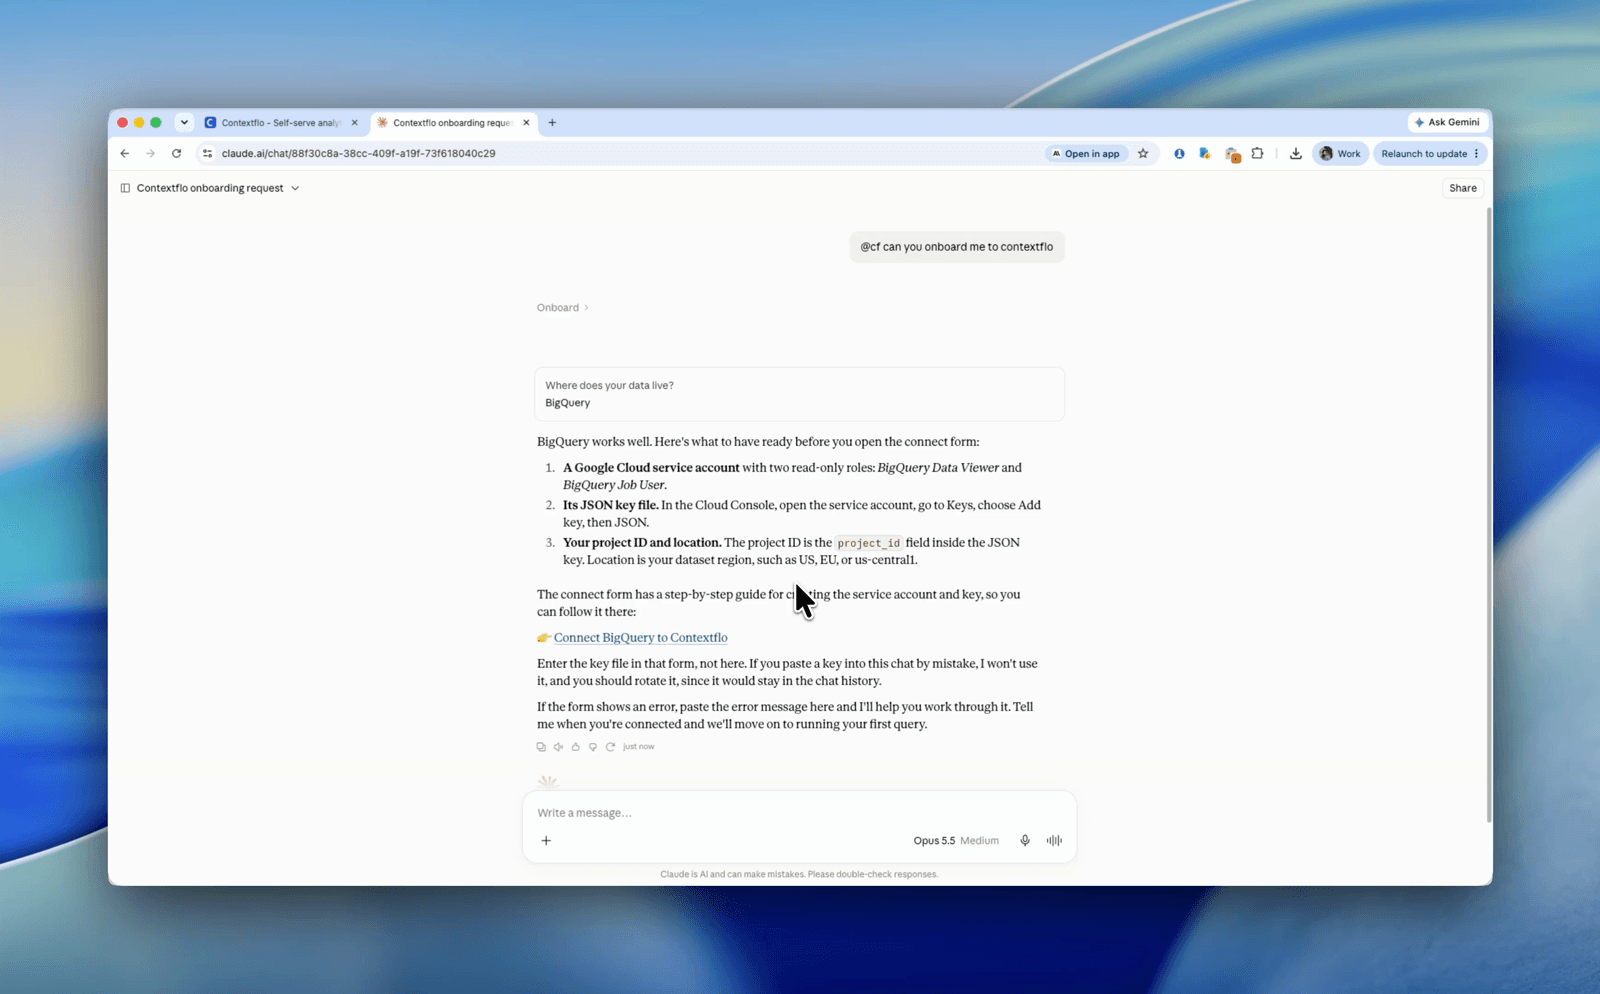
Set up Contextflo from inside Claude: onboarding is now a conversation
3 min read
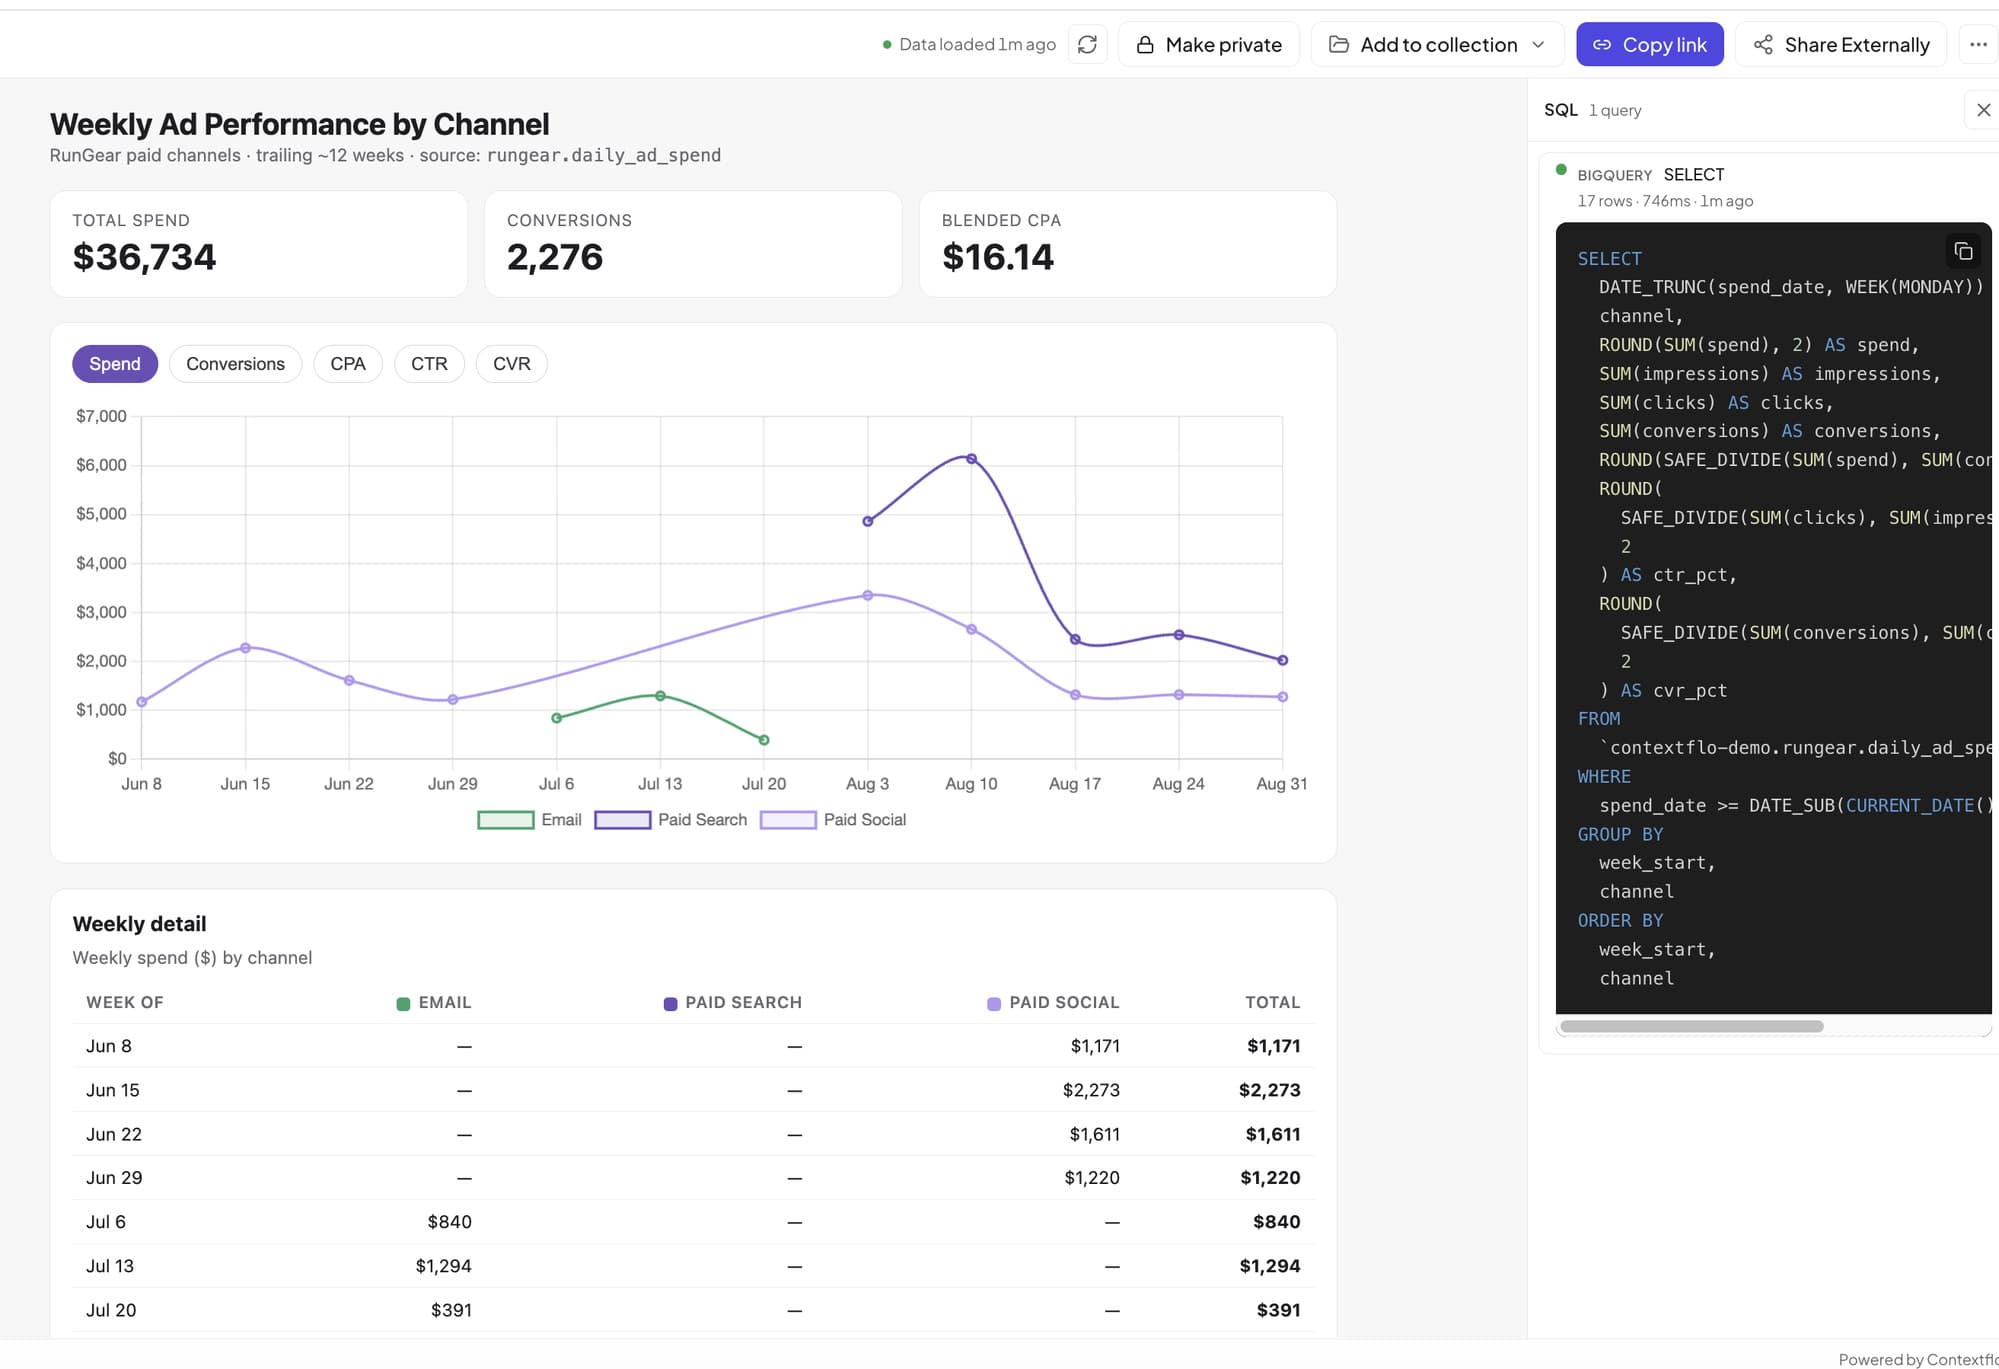
How to host and share Claude artifacts with your whole team
3 min read
The official Postgres server for Claude is archived. Here's what to use instead.
7 min read