Connecting Claude to your warehouse breaks your permissions. Here's how to put them back.
Permissions models were designed for a world where the person running the query is the person asking the question. AI analytics breaks that assumption, and most teams don't notice until something leaks.
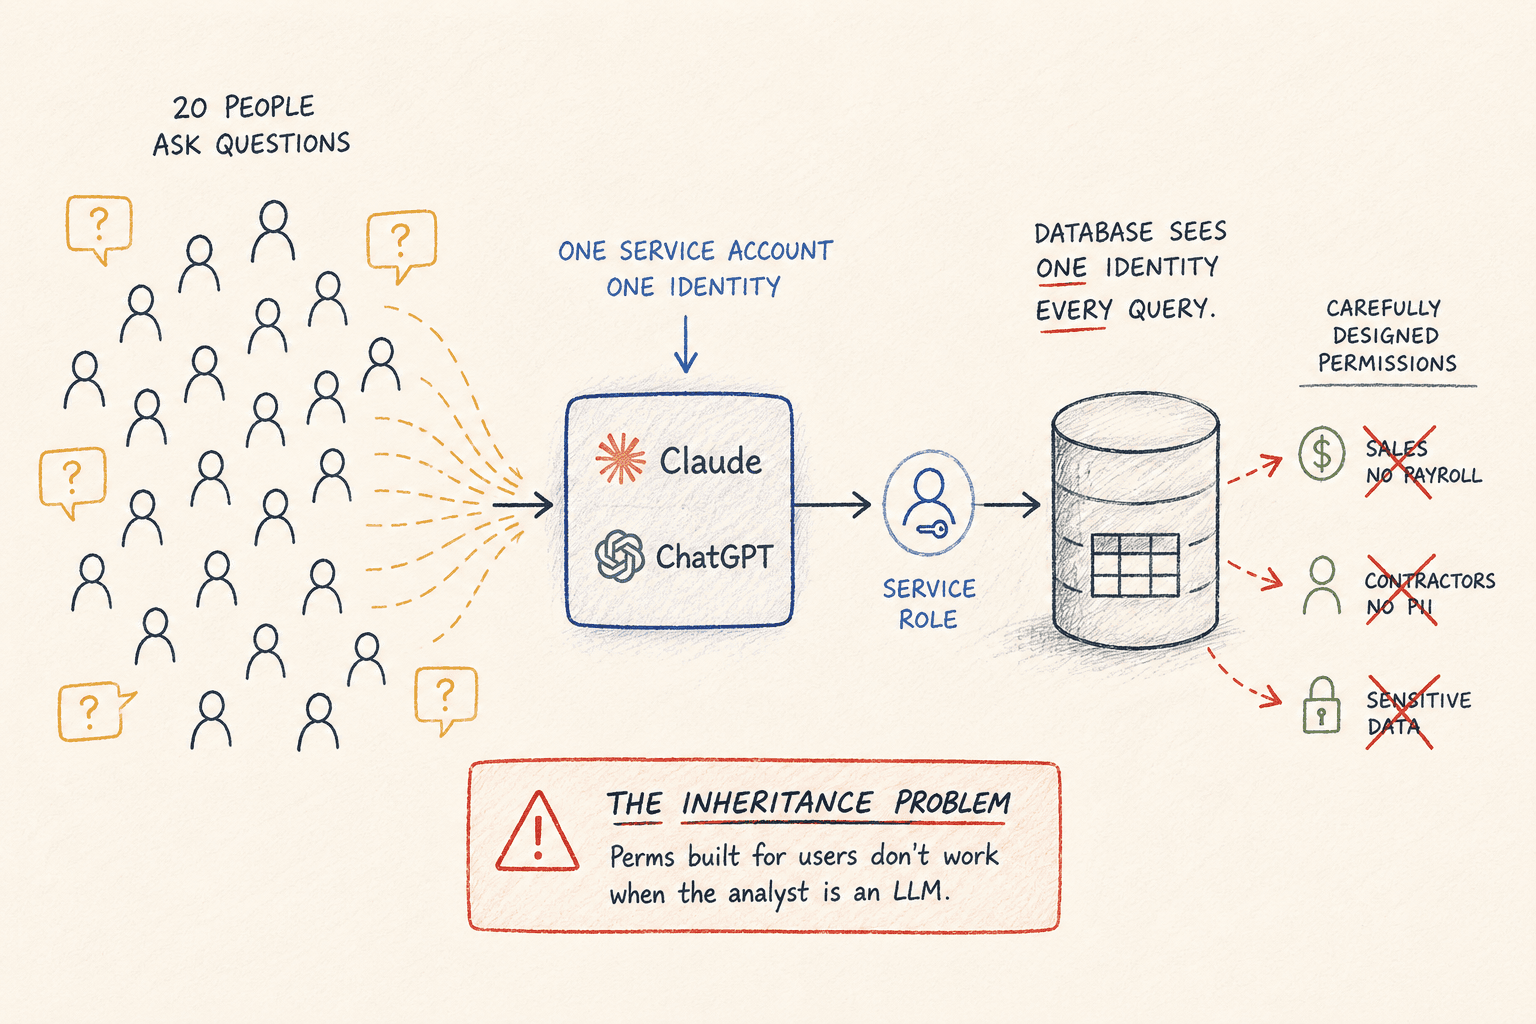
Here's the setup that breaks: your team connects an LLM to the warehouse through one service account. Twenty people ask questions through it. The database sees one identity, the service role, running every query. Your carefully designed grants, the ones that keep sales out of payroll and contractors out of customer PII, apply to exactly nobody, because nobody is querying as themselves anymore.
This is the inheritance problem, and it's the single most common security gap we see in team AI analytics setups.
Why user-level permissions break
In the traditional setup, permissions compose naturally. Maria from sales logs into the BI tool, the BI tool connects as Maria (or a role mapped to her), and the database enforces what Maria can see. Identity flows end to end.
Put an LLM in the middle and the flow snaps. The model queries on behalf of everyone, using whatever credential it was given. Three consequences:
Everyone inherits the union of all access. The service account needs to see every table anyone might ask about, so effectively everyone can ask about everything. The intern can ask about compensation. They probably won't. "Probably" is not a permissions model.
The agent explores. A human who gets "access denied" stops. An agent treats it as an obstacle. In our query logs, across 76,000+ AI-generated queries, agents hit information_schema more than 2,000 times, frequently right after an access-denied error, mapping what else they could reach. Not malicious. Agents are built to find a way. Your boundary has to be enforced at a layer the agent can't route around.
Audit collapses to one row. The database log says the service role ran 400 queries yesterday. Which human asked which question? If you can't answer that, you don't have an audit trail, you have a word count.
Two ways to put permissions back
- Give every person a real database identity and have the AI connect as them. Permissions compose cleanly, but now you're managing database users, credential rotation, and offboarding for every human and every AI surface.
- Enforce permissions in a layer above the database. Lighter, and where most teams should start.
For most teams at 10 to 200 people, that second option, table-level scoping with individual identity, covers the large majority of real access needs.
How Contextflo handles it
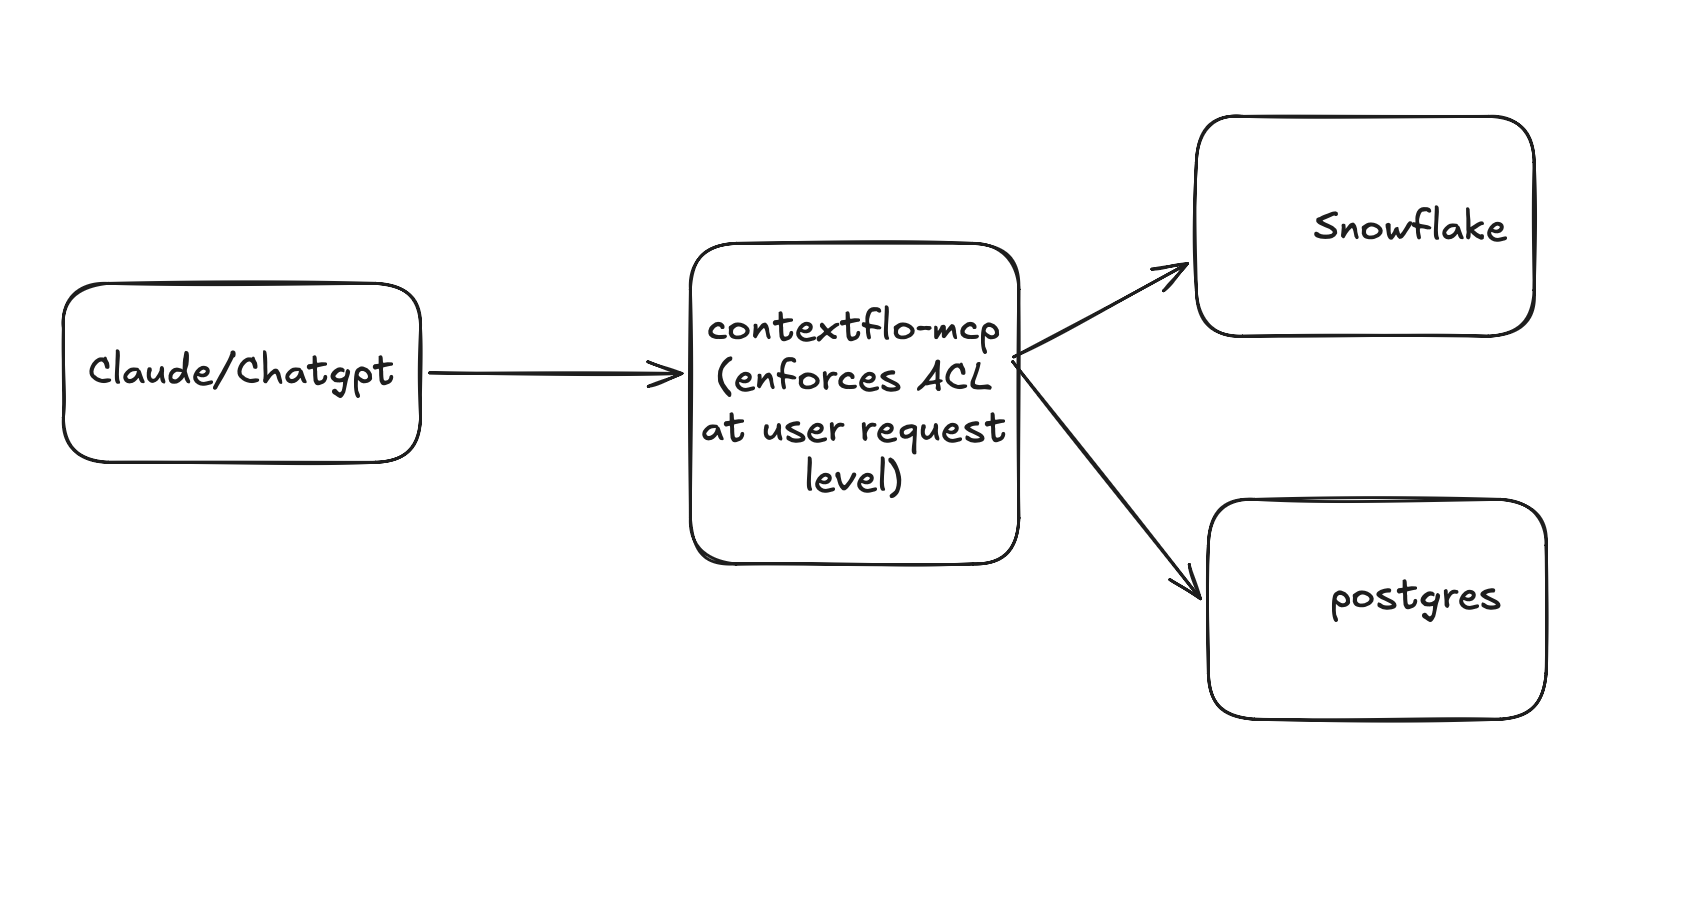
Contextflo puts a permission layer on top of your data sources. One layer, even if your data is spread across several.
The pieces
Three things to set up:
- Users: everyone who asks is authenticated as themselves, through OAuth. No shared service account.
- Groups: a group is one or more users. Sales, Finance, Contractors.
- Rules: allow-read grants attached to a group, listing which schemas and tables it can reach.
Setting it up
Say your data is organized into schemas, acme.orders, acme.deals, acme.web_events, and acme.payroll, each holding a bunch of tables. You've got a sales team, a finance team, and a couple of contractors. You set up three groups, each with allow-read rules (the .* grants every table under that schema):
- Sales (John):
acme.orders.*,acme.deals.*,acme.web_events.* - Finance (Kevin):
acme.orders.*,acme.deals.*,acme.payroll.* - Contractors (Sam, Tom):
acme.web_events.*
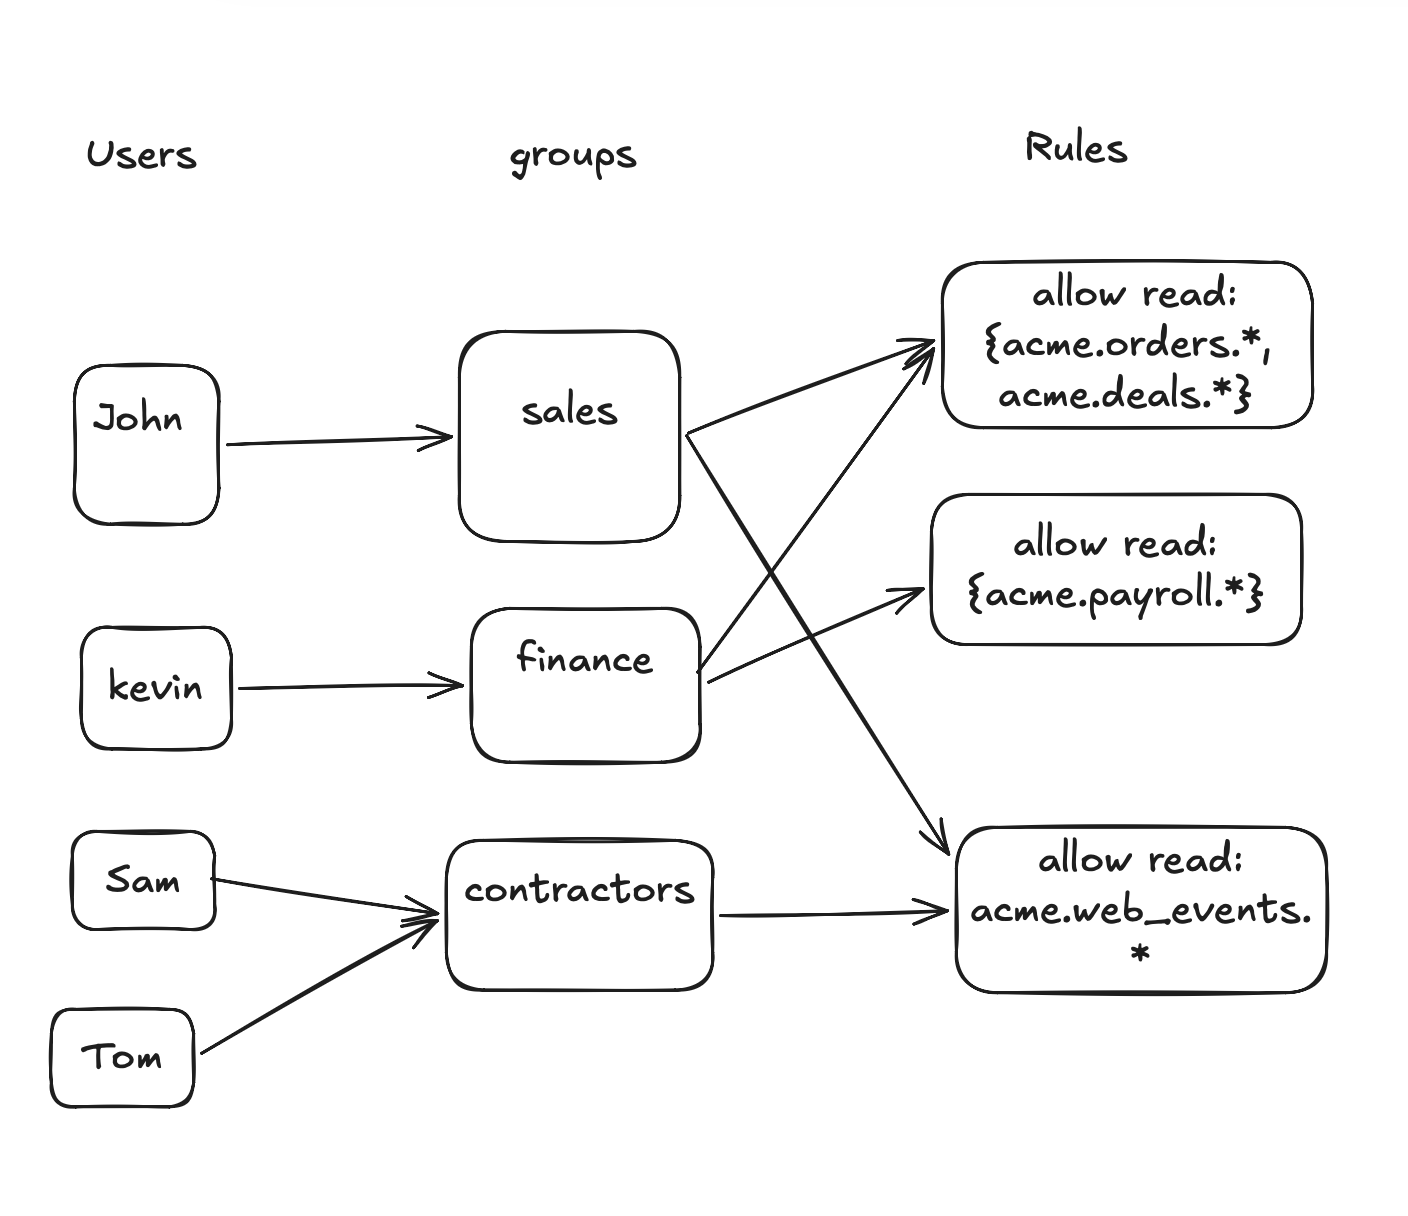
Add each person to their group, and that's the config. A new sales hire drops into the Sales group and inherits the scope. No per-user table grants, no database users to manage.
Nothing outside those rules is visible. A table no group allows is refused, and that includes tables you connect later: a rule on one table covers only that table, while a schema rule like acme.deals.* also covers new tables added to that schema.
Offboarding
Removing someone from the workspace removes them from every group, and removing them from one group takes effect on their next question. What they asked and the SQL that ran stay in the audit log with their name on it.
How it's enforced at query time
A question has to clear two checkpoints:
- What the model can see. When Sam (a contractor) asks something, Contextflo resolves his group and only exposes the tables under
acme.web_events, the one schema Contractors can read. The model planning his answer never even sees the payroll or deals schemas, so it can't reach for them. (Side benefit: a model choosing among the few tables in scope instead of all 200 is also more accurate.) - What actually runs. Say Sam gets clever: "what does everyone make?" and names a table in
acme.payrolldirectly. The model writes the SQL, but before it hits the warehouse, Contextflo checks the query against the Contractors group's rules, sees payroll is out of scope, and rejects it. He never gets the rows.
Every question Sam asked, and every query the model wrote, is logged with his name on it.
The same check covers dashboards and artifacts. Each chart re-runs its query as the person viewing it, so a dashboard shared across the company still shows Sam only what Sam can read. A chart that needs a table he can't read shows him an access error instead of the data.
The general principle stands regardless of tool: when the analyst is an LLM, identity and permissions have to live in a layer between the model and the database, because the database can no longer see who's asking, and the model will use everything it can reach.
Rows and columns: use a view
Rules work per table. A table here means anything you've connected: a Snowflake, BigQuery or Postgres table or view, an uploaded CSV, or a Google Sheet tab. Row and column limits work through views: create a view in your warehouse that shows only the right rows and columns, and give the group the view instead of the base table. The view is the Contextflo table that group queries.
Filter rows
Say each sales rep should see only their region's deals. The base table is acme.deals.opportunities, with a region column.
CREATE VIEW acme.access.deals_west AS
SELECT * FROM acme.deals.opportunities
WHERE region = 'West';
- Put the view in its own schema, here
access. If it sits next to the base table and a group hasacme.deals.*, the base table comes along with it. - Connect the view in Contextflo like any other table. Views appear in the same list as your tables.
- Give the West group a rule for
acme.access.deals_west, and no rule coveringacme.deals.opportunities. - Run Check access for someone in West. The view should be allowed and the base table refused.
Hide columns
Same idea with columns. Contractors can look customers up, but don't need email or phone in an AI answer.
CREATE VIEW acme.access.customers_contractors AS
SELECT customer_id, first_name, city, signup_date, plan
FROM acme.orders.customers;
List the columns you want instead of excluding the ones you don't. Snowflake has SELECT * EXCLUDE (email, phone) and BigQuery has SELECT * EXCEPT (email, phone), but with either one, a sensitive column someone adds next quarter shows up in the view on its own. One view can do both: filter the rows and pick the columns.
The SQL for your warehouse
Replace contextflo_reader with the role or account Contextflo connects as.
Snowflake
CREATE SCHEMA IF NOT EXISTS acme.access;

CREATE VIEW acme.access.deals_west AS
SELECT * FROM acme.deals.opportunities
WHERE region = 'West';

GRANT USAGE ON SCHEMA acme.access TO ROLE contextflo_reader;
GRANT SELECT ON VIEW acme.access.deals_west TO ROLE contextflo_reader;
BigQuery
CREATE SCHEMA IF NOT EXISTS `acme.access`;

CREATE VIEW `acme.access.deals_west` AS
SELECT * FROM `acme.deals.opportunities`
WHERE region = 'West';
Then give Contextflo's service account BigQuery Data Viewer on the access dataset. A standard BigQuery view also needs read access to the table underneath, which the service account already has if it was reading deals.
Postgres
CREATE SCHEMA IF NOT EXISTS access;

CREATE VIEW access.deals_west AS
SELECT * FROM deals.opportunities
WHERE region = 'West';

GRANT USAGE ON SCHEMA access TO contextflo_reader;
GRANT SELECT ON access.deals_west TO contextflo_reader;
Use a plain view in Postgres, not a materialized view. Contextflo reads the table list from information_schema, and Postgres leaves materialized views out of it.
Using the warehouse's own row policies
Snowflake has row access and masking policies, BigQuery has row-level access policies and column policy tags, and Postgres has row-level security. Keep them. They decide based on the database account running the query, so they set the boundary of what Contextflo can read as a whole. Within that boundary, Contextflo groups and views decide what each person sees.
Uploaded files and Google Sheets
Each uploaded CSV and each Google Sheet tab is its own Contextflo table, under the same group rules. To give teams different slices of a sheet, give each team its own tab or file.
Audit
Whatever you set up, log every query with the human attached and the question they actually asked. The natural-language question matters more than the SQL: SELECT * FROM acme.payroll.comp might be legitimate analysis or fishing, but "what does everyone on the exec team make" removes the doubt.
Here is a more in-depth look at Contextflo and how it works.
What is Contextflo?
Contextflo is a governed context layer between your data and the AI your team already uses. Connect your warehouse once, and your team asks questions in their own Claude or ChatGPT. The model writes and runs the SQL; Contextflo supplies the definitions, the per-user access control, and the audit that make the answers trustworthy. Your data never moves, and you do not need a data team.
How it works
Contextflo, explained by our founder.
Your team queries in their own Claude or ChatGPT over MCP, so you bring any agent rather than a locked-in bot, and every answer comes back with the SQL shown and access enforced per user.
FAQ
Can Claude see every row in a table? Only if the person asking has access to that table. Contextflo checks every query against the asker's group rules before it runs. To limit which rows a group sees, create a view in your warehouse with a WHERE filter and give the group the view instead of the base table. That view is the Contextflo table the group queries.
Can I hide columns like email or phone? Yes. Create a view that leaves those columns out and give the group the view, not the base table. The only table that group can reach doesn't have the columns, so neither Claude nor the person asking can query them.
Does this work for Google Sheets and uploaded CSVs? Yes. Each uploaded CSV or Google Sheet tab is a Contextflo table, governed by the same group rules as your warehouse tables. To give teams different slices of a sheet, give each team its own tab or file.
Can I use Snowflake row access policies or BigQuery row-level security instead? Yes, alongside Contextflo. Warehouse policies decide based on the database account running the query, so they set the boundary of what Contextflo can read as a whole. Within that boundary, Contextflo groups and views decide what each person sees.
Do newly connected tables become visible to everyone? No, not until a rule covers them. A table no group allows is refused, so a new table stays hidden until you allow it. The one nuance: a schema-wide rule like acme.deals.* includes tables later added to that schema, so use table rules where a team shouldn't get everything.
Does this work in ChatGPT and on dashboards? Yes. The same rules apply to every assistant connected to Contextflo, and to dashboards and artifacts, which re-run each query as the person viewing them.
See it on your own data.
Connect your warehouse and your team can ask Claude about it the same day, without waiting on a data team. Want a walkthrough first? Grab 20 minutes.
Book a 20-minute callSee how teams use Contextflo
Related posts
Keep reading
Conversational analytics: 5 ways to set it up, compared
7 min read
How to connect Claude to BigQuery, and fix the errors you'll hit
8 min read
How to connect Claude to Postgres without giving it write access
9 min read
How to build a BI dashboard with Claude that your team can actually trust
8 min read
How to give Claude read-only access to your database (it isn't always the default)
7 min read
You connected your warehouse to Claude, now what?
5 min read
ClickHouse MCP: how to connect ClickHouse to Claude, Cursor or Codex
6 min read
Query BigQuery from the Codex CLI with MCP
5 min read
Run ClickHouse queries from Codex with MCP
6 min read